Local LLMs
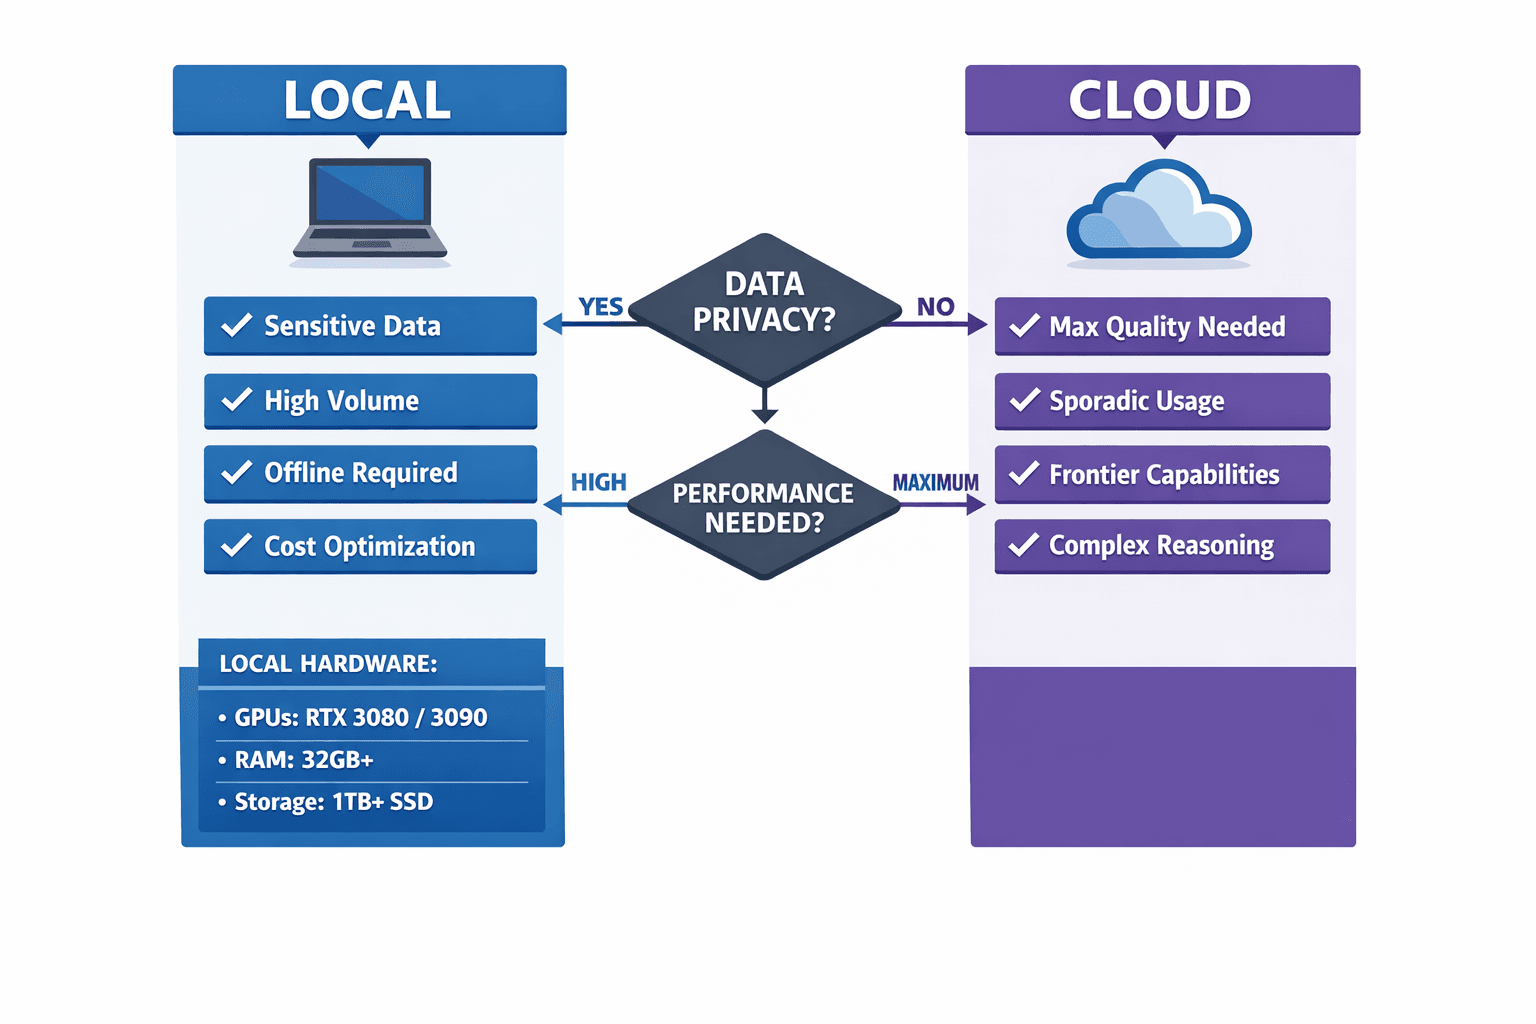
Run models on your own hardware for privacy, offline use, or very high volume. The trade-off is quality: local models trail frontier cloud models, and the gap shows most on hard reasoning and large codebases.
The real reason to go local is data, not cost. Decide which data must never leave your machines. Then measure whether local quality holds up on those tasks. Saved API spend often loses to engineer time spent fixing weaker output.
Popular models (2026)
Open-weight families worth evaluating: DeepSeek, Qwen (including Qwen Coder), Llama, Kimi, MiniMax, Mistral, and OpenAI's gpt-oss.
Inference tools
- Ollama: simplest CLI and API
- LM Studio: desktop GUI
- vLLM: production serving
- llama.cpp: CPU and Apple Silicon
Local vs cloud
| Local | Cloud |
|---|---|
| Data that can't leave | Best quality needed |
| Very high volume | Sporadic usage |
| Offline | Frontier capabilities |
| Predictable fixed cost | Complex reasoning, large codebases |
Setting up Ollama
# Install
brew install ollama                             # macOS
curl -fsSL https://ollama.com/install.sh | sh   # Linux

# Start the server
ollama serve

# Pull models
ollama pull qwen2.5-coder       # code
ollama pull deepseek-r1         # reasoning
ollama pull nomic-embed-text    # embeddings for RAG

# Run interactively
ollama run qwen2.5-coder

# OpenAI-compatible API
curl http://localhost:11434/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model": "qwen2.5-coder", "messages": [{"role": "user", "content": "Hello"}]}'
From Python (OpenAI SDK pointed at Ollama):
from openai import OpenAI

client = OpenAI(base_url="http://localhost:11434/v1", api_key="not-needed")
response = client.chat.completions.create(
    model="qwen2.5-coder",
    messages=[{"role": "user", "content": "Explain recursion"}],
)
print(response.choices[0].message.content)
Hardware requirements
| Model size | RAM | GPU VRAM | Quality |
|---|---|---|---|
| 3B | 4GB | 4GB | Simple tasks |
| 7-8B | 8GB | 8GB | Balanced |
| 13-14B | 16GB | 16GB | Good |
| 30-34B | 32GB | 24GB | High |
| 70B | 64GB | 48GB+ | Best local |
Apple Silicon: unified memory means RAM is VRAM. Pro chips handle ~14B comfortably, Max ~34B, Ultra 70B.
Model selection guide
| Use case | Model family | Why |
|---|---|---|
| Code completion | Qwen Coder, DeepSeek Coder | Trained on code |
| General chat | Llama, Mistral | Good balance |
| Long context | Kimi, Qwen | Large context windows |
| Embeddings | nomic-embed-text | Fast, good quality |
| Reasoning | DeepSeek R1 | Chain-of-thought |
Using local LLMs with Claude Code
Route by data sensitivity and difficulty: local models for private or simple work, cloud for everything that needs frontier quality.
def route(prompt: str, sensitive: bool):
    if sensitive:
        # Never leaves the machine
        return ollama.chat.completions.create(model="qwen2.5-coder", messages=[...])
    return anthropic.messages.create(model="claude-sonnet-5", max_tokens=16000, messages=[...])
Own local models like infrastructure: someone patches, upgrades, and monitors them. Never mix local and cloud models in one workflow without knowing exactly which data goes where.